
By Artem Korsakov ·
In short: automation effectiveness is assessed on the same tasks before and after implementation. Time for review, corrections, exceptions and support is taken into account. Freed-up hours show additional team capacity, while the financial effect depends on how the company uses it.
A nice demo answers the question of whether the system can perform an action. A manager needs one more answer: has it become more convenient and more profitable to do the real work? That requires a baseline and a comparable check.
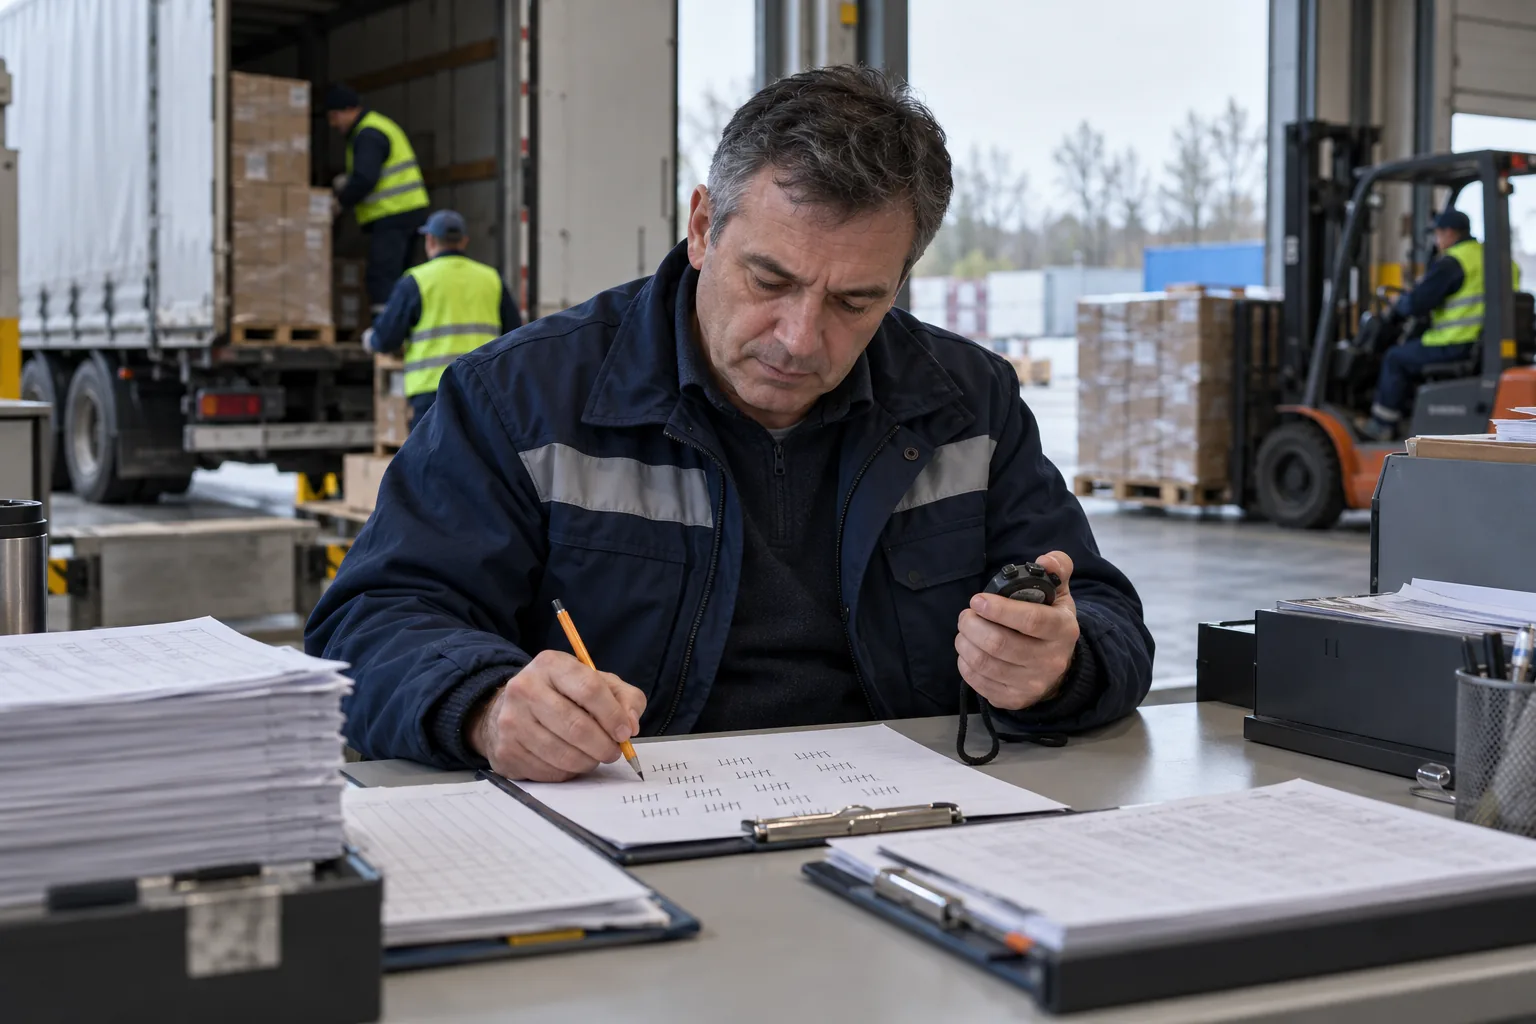
Record current labour costs
Choose one operation and measure it the same way each time. For handling a request, this could be the time from opening the email to a finished, verified card. Waiting for a client's reply is better counted separately; otherwise the metric will include time the system barely affects.
Collect regular and difficult cases. It is important to see which tasks take up most of the time. An average across a few of the simplest emails does not describe the whole flow.
Also note re-entry of data, corrections and requests without an owner. These signs can be more useful than a general promise to “increase productivity”.
Count the full path after implementation
Automation can prepare a draft quickly, but an employee then reads, corrects and confirms it. All these actions count as labour. So do manual handling of exceptions and investigating failures.
If a task now takes less time, check whether part of the work has shifted to another employee. For example, a manager stopped filling in the card, but a dispatcher now spends time correcting the assignment.
Quality must also remain comparable. A faster result with wrong terms is not a successful implementation.
An example time calculation
Take a hypothetical 240 requests a month. Manual processing takes 10 minutes on average, that is, 40 hours. After setup, preparation and review take 6 minutes, or 24 hours. Another 4 hours a month go on exceptions and monitoring.
In this illustrative example, the difference is 12 hours: 40 − 24 − 4. The example is for illustration; its figures do not transfer directly to your business. A project uses its own measurements.
If the number of requests or their complexity changes, the comparison must be recalculated. The resulting difference cannot be applied to any volume without checking.
Illustrative calculation of the full time for 240 requests before and after automation. Before implementation: 40 hours. After: 24 hours for preparation and regular review, plus 4 hours for exceptions. The difference is 12 hours; the financial effect is assessed separately.
What time savings mean
An employee can use the freed-up time for additional requests, work with clients or other tasks. Their pay does not necessarily decrease.
That is why it is useful to record the effect separately: less overload, faster response, more tasks processed or costs that have actually changed. Expected additional revenue remains a hypothesis until it is confirmed by results.
To assess the full budget, launch, services, model use and support are taken into account. A payback calculation is built on the company's confirmed data. A general “AI savings” figure is not suitable for this.
How to check that the average does not hide a problem
Split requests into a few clear groups: regular, incomplete, with an attachment and with changed terms. Compare time and errors within each group. Otherwise a growing share of simple requests could be mistaken for the effect of automation.
In the illustrative calculation above, the 6 minutes cover preparation and regular review of each request, and the 4 hours are added only for separate work on exceptions and process monitoring. If exception time is already included in the average 6 minutes, it must not be added a second time. Before measuring, agree on what each metric includes.
AI can gather the reasons for corrections from comments, group them and propose a summary with links to specific cards. An employee checks the categories; the system counts the number of cases and durations from the records. The assistant must not invent missing measurements for the sake of a nice report.
Training example: AI groups the reasons for corrections, and the system counts the cases. The groups of reasons are suggested by AI and edited by an employee. The number of cases in each group is counted by the system from the records.
When usefulness is confirmed enough for the next step
Look at several comparable working periods and at whether the team uses the product without constant reminders. If an employee keeps a parallel spreadsheet, find out why: data is missing, correcting an error is inconvenient, or the manager still demands the old report.
An approach to measuring and managing AI risks is set out in the NIST AI RMF Playbook. It does not give a universal savings percentage. Specific metrics and the decision to expand remain with the process owner.
Further implementation needs three answers: which result has improved, how much it costs to maintain and what still has to be done manually. Also write down the conditions under which the effect would disappear, for example a change in the mix of incoming documents. Such an assessment is more useful than a single payback figure that cannot be repeated next month.
How to check the result of implementation
A small set of agreed metrics is enough:
- time per verified task;
- share of output that requires correction;
- number of unprocessed exceptions;
- service costs for the same period;
- actual use of the solution by the team.
The threshold at which the project is considered useful is set by the process owner. After the check, you can expand the scenario, change it or stop further work.
At trike_dev, you can start with one task and agree on how the result will be checked. See the data transfer example and request approvals. The boundaries of a future solution are worth testing on a prototype before development.
Related reading: Automation budget: how to choose a project and avoid overpaying; Implementing AI in business: how to test one task in a pilot.
Частые вопросы ### Can a specific savings percentage be promised in advance?
Your process needs baseline data and a check. Other companies' results and a demo do not give a reliable basis for such a promise.
If little time is saved, is the project useless?
Not necessarily. Sometimes it is more important to reduce the number of lost requests or make actions verifiable. This result also needs to be defined and measured in advance.